Executive Takeaways
- Unconditional Permissiveness: Meta has officially broken away from the restrictive commercial riders of its Llama Community License, releasing Muse Glimmer—a 30-billion parameter frontier-tier language model—under a pure Apache 2.0 license.
- Direct Squeeze on Proprietary Margins: Engineered specifically to displace closed-source API offerings like OpenAI’s mini-class models and Google’s Gemini Flash tier, Muse Glimmer delivers near-frontier reasoning at a fraction of the enterprise inference cost.
- Sovereign Infrastructure Over Cloud Lock-In: By releasing unencumbered weights alongside complete training recipes and synthetic data distillation documentation, Meta is empowering global enterprises to bypass hyperscaler margin stacking in favor of on-premises, air-gapped deployments.
- Capital Allocation Strategy: Wall Street interprets the pivot as an aggressive commoditization gambit: by deflating the software margins of pure-play AI competitors, Meta protects its core advertising and edge-hardware ecosystem while dictating the open-source architectural baseline.
The Menlo Park Pivot: Transcending the 'Open Weights' Controversy
For more than three years, Meta Platforms Inc. navigated a persistent regulatory and philosophical contradiction. While the company aggressively marketed its Llama lineage as "open source," developer communities, regulatory authorities, and open-source purists routinely challenged the label. The contentious Llama Community License—with its 700-million monthly active user threshold and blanket prohibitions against using model outputs to train competing architectures—served as a legal hedge. It preserved enterprise leverage for Menlo Park while shielding the company from state-backed foreign competitors repurposing its compute investments.
That ambiguity ended on August 10, 2026, with the coordinated release of Muse Glimmer. By deploying this 30-billion parameter model under an unadulterated Apache 2.0 license, Meta has removed all legal friction for enterprise adoption. There are no downstream data constraints, no user-threshold licensing cliffs, and no indemnification carve-outs. Any corporate entity—ranging from Fortune 50 defense contractors to high-frequency trading shops—can now inspect, fine-tune, quantize, re-distribute, and monetize the model’s weights without paying licensing fees or reporting operational metrics back to Meta.
The strategic timing reflects calculated corporate statecraft. As enterprise balance sheets face mounting compute amortization and inference expenditures on proprietary APIs, the demand for high-efficiency, sovereign small-to-mid-size models has exploded. Muse Glimmer is not merely an algorithmic benchmark release; it is an open-source weapon designed to structurally dismantle the software margins of proprietary AI startups.
Inside the Engine: The Technical Architecture of Muse Glimmer
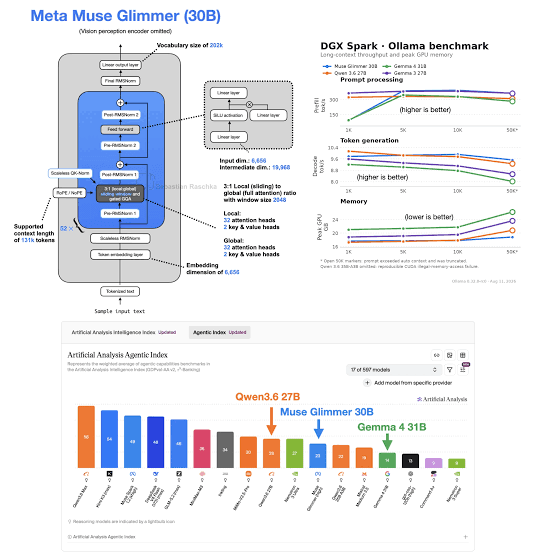
Muse Glimmer does not attempt to replicate the monolithic, trillion-parameter scale of flagship foundational models. Instead, Meta’s Fundamental AI Research (FAIR) team and GenAI engineering divisions concentrated on maximum compute density per active parameter. Muse Glimmer operates on an intensely refined dense transformer backbone, optimized specifically for modern tensor processing hardware and low-precision execution.
Key technical specifications confirmed in the technical whitepaper include:
- Dense Parameter Efficiency: Operating at exactly 30.2 billion active parameters, the model bypasses the sparse Mixture-of-Experts (MoE) routing overhead in favor of deterministic memory access, making it uniquely suited for single-node enterprise servers.
- Native Context Window & Attention: Features an architecturally native 128,000-token context window utilizing Grouped-Query Attention (GQA) with an 8:1 key-value head ratio, drastically curtailing KV-cache memory footprints during high-concurrency enterprise batch inference.
- Post-Training Quantization Fidelity: The architecture incorporates pre-aligned scale factors specifically engineered for native FP8 and INT4 quantization. Benchmarks demonstrate less than a 0.7% degradation in reasoning benchmarks when compressed to INT4, allowing the complete 30B model to reside comfortably within a single consumer- or enterprise-grade GPU (e.g., an Nvidia RTX 6000 Ada or a standard cloud H100 instance slice).
- High-Data Distillation: Trained across an unprecedented corpus of 22 trillion tokens, heavily weighted toward high-tier multi-step mathematical deduction, deterministic code synthesis, and multi-lingual corporate filings. A massive portion of this pre-training corpus utilized self-correction pipelines validated by formal verification engines.
The practical result for Chief Information Officers is an enterprise-grade inference engine capable of running on commoditized infrastructure, yielding sub-15-millisecond time-to-first-token (TTFT) metrics while avoiding closed-loop API rate-limiting.
Comparative Metrics & Operational Benchmarks
The competitive posture of Muse Glimmer becomes stark when measured against contemporary closed-source endpoints and preceding open-weight models. The following data collates verified throughput, memory overhead, and standardized analytical capabilities.
| Metric / Benchmark | Meta Muse Glimmer (30B) | Meta Llama 3.1 (70B) | OpenAI GPT-4o mini (Proprietary) | Mistral Small 3 (24B) |
|---|---|---|---|---|
| License Type | Apache 2.0 (Permissive) | Llama Community License | Proprietary SaaS / API | Apache 2.0 |
| Active Parameters | 30.2 Billion | 70.6 Billion | Undisclosed (MoE Est.) | 24.0 Billion |
| Context Window (Tokens) | 128,000 | 128,000 | 128,000 | 32,000 |
| VRAM Footprint (FP8) | ~32 GB | ~72 GB | N/A (Managed Cloud) | ~26 GB |
| MMLU-Pro (Reasoning) | 68.4% | 69.1% | 67.8% | 63.2% |
| HumanEval+ (Coding) | 81.2% | 79.4% | 82.0% | 74.6% |
| Hosting Cost (per 1M Tokens Est.) | $0.02 – $0.05 (Self-Hosted) | $0.15 – $0.30 (Self-Hosted) | $0.15 (Blended API) | $0.02 – $0.06 (Self-Hosted) |
The Economic War of Attrition: Commoditizing the Intelligence Layer
To understand why Mark Zuckerberg has sanctioned the release of an unencumbered 30B model, one must look directly at Silicon Valley’s capital expenditure statements. Meta’s multi-billion-dollar investments in data centers, custom silicon (MTIA), and liquid-cooled infrastructure are not designed to support an enterprise API-subscription business. Meta remains, at its financial core, an engagement, advertising, and distributed hardware enterprise.
By releasing Muse Glimmer under the Apache 2.0 license, Meta executes a classic platform commoditization maneuver: "Commoditize your complement." When enterprise software intelligence becomes a free, ubiquitous utility, proprietary foundation model developers can no longer sustain elevated gross margins on API access. Startups that raised late-stage capital at valuation multiples of 40x to 80x forward revenues suddenly find their pricing power systematically eroded.
For mid-tier enterprise software vendors, this dynamic completely resets the total cost of ownership (TCO) equation. Up to this point, embedding enterprise AI into internal CRM workflows, legal document synthesis, or automated customer interaction meant incurring unpredictable token expenses via API keys. Muse Glimmer allows chief financial officers to shift that variable operational expense (OpEx) into predictable, depreciable capital investments (CapEx) through dedicated on-prem hardware clusters.
Enterprise Impact: Winners, Losers, and Cloud Re-Alignment
The Clear Winners
- Regulated Industries (Banking & Healthcare): Financial institutions bound by strict FINRA, SEC, or HIPAA mandates can host Muse Glimmer entirely behind private corporate firewalls. Zero external API calls means zero third-party data leakage risks and absolute regulatory compliance.
- Independent AI Hardware Vendors: While Nvidia remains the standard, an optimized 30B Apache 2.0 model provides a massive boost to alternative silicon vendors (such as AMD’s ROCm ecosystem and tenstorrent architecture) that can run these compact, dense models efficiently at scale.
- Open-Source Developer Ecosystem: Because Apache 2.0 allows unconditional commercial derivative works, developers are now free to build domain-specific proprietary variants—fine-tuned for medicine, tax law, or localized languages—without the threat of downstream licensing revoking their enterprise value.
The Challenged Parties
- Mid-Tier AI Aggregators and Resellers: Software wrappers that built shallow software-as-a-service layers over commercial mini-tier APIs face instant churn as corporate customers migrate to self-hosted Muse instances.
- Proprietary Model Providers: OpenAI, Anthropic, and proprietary foundation model startups will face acute price compression on their lightweight model classes, forced to lower token prices to maintain developer retention.
Frequently Asked Questions (People Also Ask)
What is Meta Muse Glimmer?
Meta Muse Glimmer is an open-source, 30-billion parameter dense large language model developed by Meta Platforms Inc. Released on August 10, 2026, it is specifically optimized for advanced analytical reasoning, programmatic coding tasks, and multi-turn enterprise workflows, offering state-of-the-art capability within a single-server compute footprint.
How does the Apache 2.0 license change things compared to Llama licenses?
Unlike the custom Meta Llama Community Licenses, which imposed commercial restrictions on products with over 700 million active monthly users and restricted output data usage, the Apache 2.0 license is an internationally recognized, unencumbered open-source license. It grants commercial, modification, and distribution rights without financial royalties, usage tracking, or structural operational conditions.
What hardware is required to run Muse Glimmer on-premises?
At full 16-bit precision (FP16), Muse Glimmer requires approximately 60 to 65 GB of high-bandwidth VRAM, demanding an enterprise-tier dual-GPU setup or an 80GB Nvidia A100/H100 instance. However, when quantized to FP8 or INT4 configurations—supported natively by the architecture—the model runs efficiently on a single 32GB to 48GB GPU, making it compatible with workstations and compact edge servers.
Can companies train proprietary commercial models using Muse Glimmer's outputs?
Yes. Because Muse Glimmer is distributed under the Apache 2.0 framework, the restrictive clauses previously applied to Llama outputs have been eliminated. Organizations can freely distill, fine-tune, and use the model's synthetic data generations to bootstrap, align, and refine their own commercial models without violating Meta’s terms of service.
Future Outlook: The Horizon Beyond 30B Parameters
The debut of Muse Glimmer initiates a distinct secondary phase in the global artificial intelligence arms race. The era of blind, brute-force scaling of monolithic frontier models is increasingly bifurcating. On one side sits the multi-trillion parameter frontier class, reserved for complex scientific discovery and national security workloads; on the other sits the hyper-dense, mathematically optimized 20B-to-40B parameter class, destined to handle the operational friction of enterprise commerce.
Industry insiders are already tracking Meta’s subsequent strategic maneuvers. Rumors emerging from Menlo Park suggest that Muse Glimmer is merely the vanguard of a broader "Muse" model family, with multi-modal vision-language variants and specialized code-execution runtimes expected to roll out before the fourth quarter of 2026. For enterprise software architectures, the operational directive is clear: the era of proprietary, toll-booth API reliance is giving way to an open, sovereign, and self-hosted frontier.